The Compounding Cost of Deferred Infrastructure Upgrades
Unpaid infrastructure debt accrues interest that compounds across systems, processes, and people.
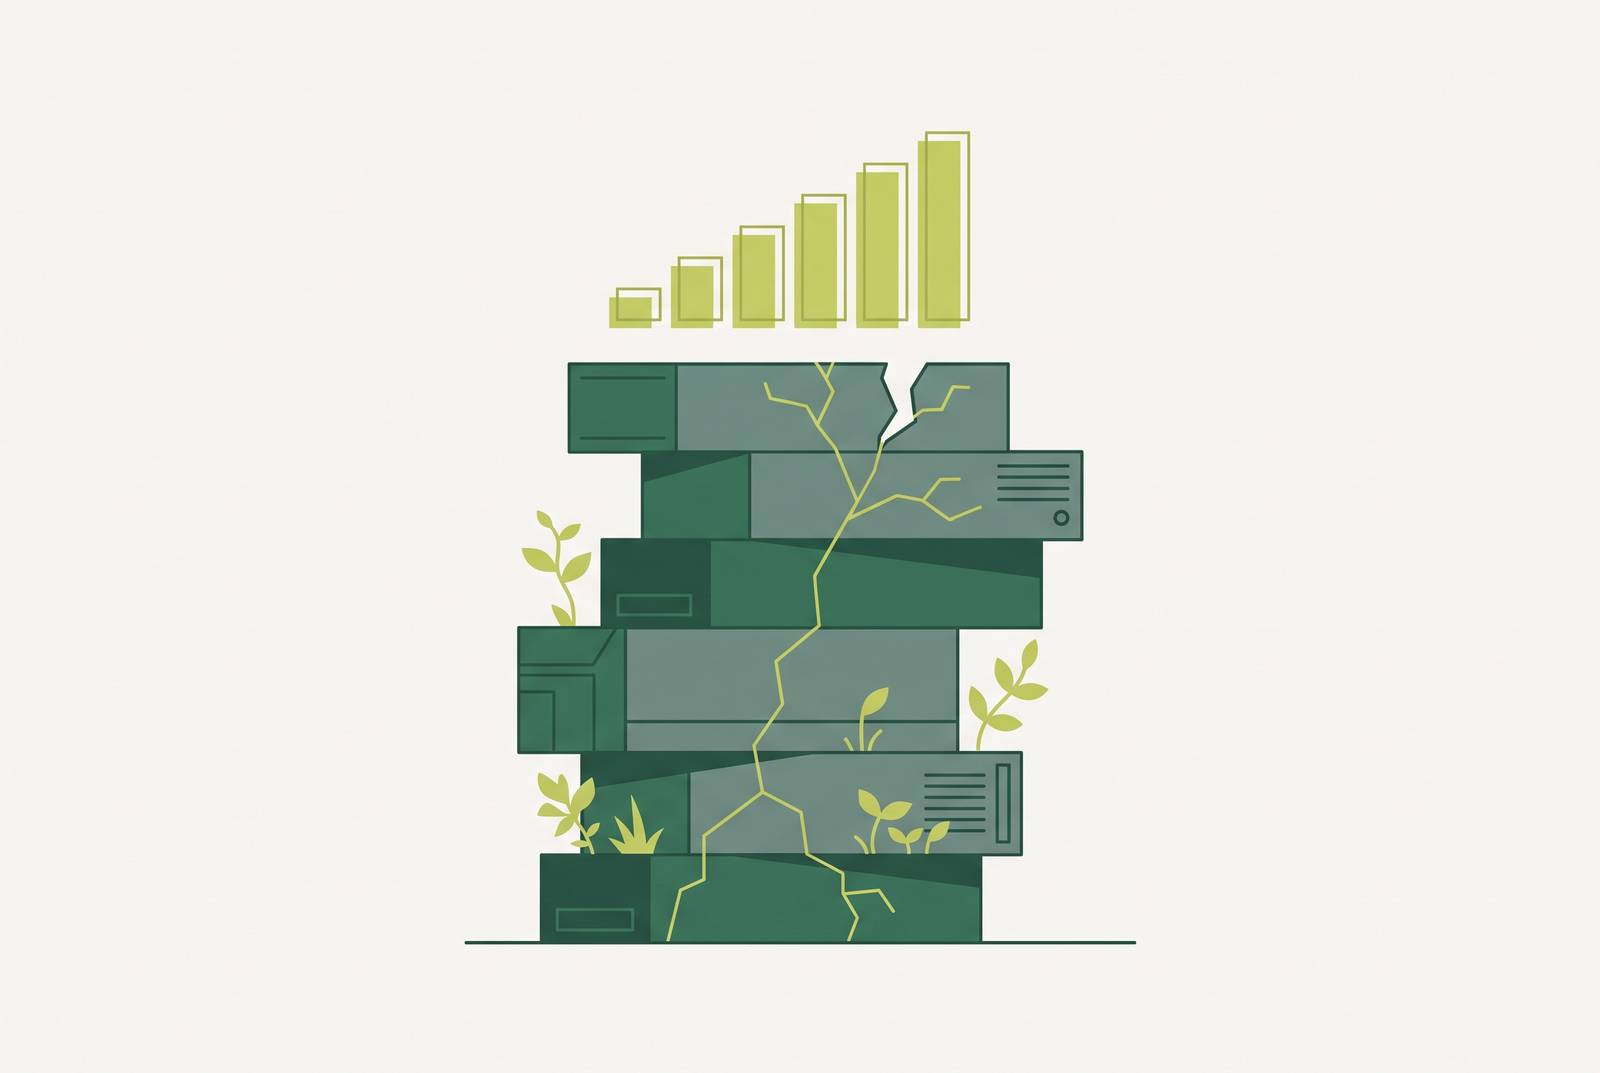
Deferred infrastructure upgrades behave like unpaid debt on a credit card, not like a to-do list that sits quietly until someone gets around to it. Skip a payment, and the balance doesn't just wait for you. It accrues interest, and that interest starts generating interest of its own(). The same mechanism runs in a codebase or a data pipeline that nobody has touched in three years. Each shortcut taken to ship faster becomes principal. The ongoing cost of living with that shortcut, the extra time every engineer spends working around it, becomes interest, and left alone, that interest compounds against future work rather than sitting still().
What makes this distinct from a normal technical to-do list is how far the damage spreads. Ordinary technical debt lives in code. Modernization debt, the broader version of this problem, touches five separate dimensions at once: systems, processes, data, integrations, and organizational capability(). Defer an upgrade in one of those five, and the other four don't stay put waiting for it. They degrade in step, because modernization debt spans systems, processes, data, integrations, and organizational capability, so deferring an upgrade in one dimension degrades the others().
Why does this stay hidden for so long? Because compounding debt is invisible right up until it isn't. The debt was always there. The threshold event just makes it impossible to keep ignoring.
The four cost layers and how each layer feeds the next
Four things happen when infrastructure debt goes unaddressed, and none of them happen in isolation. Maintenance bloat comes first, then it eats engineering capacity, which shows up as lost productivity, which delays the projects leadership actually cares about, which raises the odds of a failure serious enough to make headlines(). Treating these as four separate problems, each solvable on its own timeline, misses the point entirely, since shortcuts taken now accrue interest in the form of mounting maintenance effort, and that interest itself accrues interest, arriving in four layers (maintenance bloat, lost productivity, delayed projects, and catastrophic failure risk) that compound on each other, not in isolation. They're one problem wearing four faces, and fixing layer three without touching layer one just buys time.
Start with maintenance bloat. As a system ages without real investment, every change costs more than the last one because engineers now have to navigate a maze of existing constraints instead of just improving what's there(). Gartner's research on the subject found that organizations that let technical debt sit spend materially more on upkeep than the ones that address it while it's still small, and that gap in spending is budget that should have gone toward something new instead of quietly funding the debt's interest payments(). The extra time every engineer spends working around a shortcut produces recognizable effects, including the module nobody wants to touch because every change to it breaks something unrelated, the manual workaround buried three steps deep in someone's weekly routine, and the custom integration that only one person understands, and that person left the company last spring.
That bloat becomes lost productivity almost by definition. Engineers spend their hours navigating the mess instead of building anything new, and in organizations running long-lived legacy systems, that drag can eat up roughly two-fifths of developer time in the worst cases(). A meaningful chunk of that is what the Google SRE Workbook calls "toil": repetitive manual operational work that keeps the lights on but builds nothing lasting, and toil itself is usually a symptom of automation debt that someone decided to defer a while back(). The lost time traces back to specific, identifiable causes. It's the direct, traceable output of the constraints piling up one layer below.
Lost productivity, in turn, delays the projects that matter most, and right now, the project that matters most to a lot of leadership teams is AI. Companies running on fragmented or outdated systems are considerably more likely to hit delays rolling out AI initiatives, according to McKinsey's research(). DXC described the shift this way: technical debt used to be a cost that slowed things down, one leaders could absorb and work around(). Once it starts blocking AI adoption, technical debt becomes a strategic liability because it can no longer be absorbed().
Left running long enough, that liability becomes catastrophic failure risk. Predictions cited by ITConvergence put the majority of organizations on track to face systemic failures from unmanaged technical debt by 2027. The GAO's 2025 report on federal systems shows critical government systems still running on outdated programming languages, unsupported hardware, and software with known security holes(). That's not an IT inconvenience. That's the compounding cascade reaching its final layer.
How the cascade accelerates in post-MVP and post-acquisition environments
Two moments predictably speed this whole process up: the transition out of MVP, and the aftermath of an acquisition. Both share the same underlying shape. Real-world load lands suddenly on infrastructure that was built for a smaller, simpler version of the business, and debt that felt perfectly manageable the week before becomes acute almost overnight.
MVPs get built for speed, not durability, and that's the right call when the goal is proving an idea works. But real users don't grade on a curve the way an MVP timeline does, and a system that buckles under growth can trigger a replatforming project costing millions, dwarfing whatever was saved by cutting corners early on(). The compressed timeline that skipped QA, skipped documentation, skipped architectural stability, all in the name of shipping faster, costs far more to unwind later than it would have cost to build right the first time().
Acquisitions accelerate the same dynamic from a different angle. M&A activity climbed sharply in early 2026, and DXC's research points out that every acquisition stacks another incompatible system on top of an already fragmented environment, feeding the exact debt that keeps organizations from moving fast on AI(). DXC's own framing cuts to the real reason this keeps happening: leaders aren't ignoring the debt out of negligence. Addressing it has always meant disruption nobody wanted to sign up for, and that calculus is what's now changing().
There's a second, quieter compounding effect buried in every acquisition, and it's organizational rather than technical. The team that inherits a system through M&A often doesn't understand how that system actually works, which means blind spots accumulate faster than anyone tracking the technical debt alone would expect(). Knowledge, in other words, is itself an infrastructure asset, and losing it compounds the same way an unpatched server does.
Budget-term costs of compounding across organization sizes
None of this stays theoretical once it hits a budget. Technical debt appears in budgets as real dollars, crowding out growth spending at every organizational scale(). Picture a mid-sized company with a modest IT budget, the kind that funds a handful of engineers and a few vendor contracts. A meaningful share of that budget already goes to maintenance driven by technical debt, money that was earmarked, at least in spirit, for growth initiatives before the debt claimed it().
It rarely appears in the budget as a clean line item labeled "technical debt." Budget questions get vague answers, answers like "legacy systems need more maintenance" or "support tickets are taking longer than they used to." Those answers feel fuzzy because they're symptoms being mistaken for causes().
Scale the same dynamic up, and the aggregate numbers get large enough to feel abstract, but they confirm the small-business math rather than replacing it. Accenture's research puts the aggregate cost of technical debt to U.S. companies in the trillions annually, a figure that reflects how many deferred decisions are sitting unpaid across the entire economy at once(). It's already owed(). IDC's research adds a related wrinkle: a large share of IT leaders point to technical debt as a major driver of overspending on cloud and digital infrastructure, and the cost isn't confined to maintenance budgets. It bleeds straight into the cloud bill too().
The real insight sitting underneath all of these numbers is "see more." It's "see more." Technical debt is a visibility problem first. It's a visibility problem first, and the fix starts with knowing exactly where the debt lives before a single additional dollar gets spent chasing it(). According to McKinsey, as cited in Function-4, a significant share of CIOs report that more than a fifth of their technology budget is diverted to resolving tech debt, money that never touches strategic initiatives.
Nonprofits as the sharpest case of compounding debt under constrained conditions
Nonprofits run through the exact same compounding mechanism as any company, but under conditions that make every layer of the cascade hit harder. Budgets are tighter, so early investment is harder to justify against immediate program needs. Decision-making tends to be reactive rather than planned. And when the cascade finally reaches its catastrophic-failure layer, the people who absorb the consequences are the populations the nonprofit exists to serve. They're the populations the nonprofit exists to serve.
A survey from Straight Edge Technology laid out the top IT challenges nonprofits report: cybersecurity threats, limited budgets, outdated systems, staff who never got proper training on the tools they use every day(). Read individually, these look like four separate problems a nonprofit might tackle one at a time as funding allows. They're not separate. They compound. Limited budgets produce outdated systems. Outdated systems create security threats. Security threats land hardest on staff who were never trained to spot them().
The pattern behind most nonprofit technology decisions makes this worse. Decisions tend to happen in response to something rather than as part of any plan: a staff member asks for a new tool, a grant comes through with strings attached, something breaks, or a vendor shows up with a pitch. Each decision makes sense on its own. Stack years of them together, though, and the result is an environment nobody fully understands and nobody formally owns.
The security angle deserves particular weight here. Bhaskar Jayakrishnan of Cisco points out that a single unpatched operating system, or one legacy software integration sitting at the edge of a network, gives attackers an entry point for lateral movement and privilege escalation toward the most sensitive data a network holds(). In a nonprofit, that sensitive data usually means donor records, client files, program data tied to people in vulnerable circumstances. The stakes are concrete, tied to the trust and safety of the people whose data is on the line. They're the trust that keeps the organization's mission functioning at all().
Something is shifting on the funding side that should change how nonprofits approach all of this. As of May 2026, foundations are increasingly turning down applications that ask for standalone computers or one-off hardware purchases, pushing instead toward funding long-term IT capacity(). The old model, where a nonprofit patches together whatever grant money happens to be available for whatever tool happens to be failing that quarter, is running into a funder expectation that looks more like an actual infrastructure strategy. Airtable is one of the clearest places that reactive pattern shows up in practice, a tool almost every small organization has used at some point.
Airtable as a proxy for how deferred tool migration compounds into a re-architecture bill
Airtable earns its adoption honestly. It's fast to set up, flexible enough to model almost any workflow, and it asks nothing of a small team beyond a bit of patience learning the interface. That's exactly why it becomes a textbook case of infrastructure debt at the tool layer: adopted because it removes friction early on, it slowly turns into a liability as workflows get more complex, teams grow past what it was designed for, and the cost of staying starts to outweigh the cost of leaving(). The migration keeps getting pushed off precisely because it's disruptive, and every month of delay adds to the eventual exit penalty().
The mechanics of that compounding are specific. As automations pile up, integrations multiply, and the user count climbs, Airtable's cost curve rises with it, and its permission model starts creating real security exposure: giving a volunteer or an outside partner access to one table often means handing them access to the entire workspace, because the granularity is built only for broad, workspace-level sharing(). That's a structural limitation, not a configuration mistake, and it gets worse, not better, the more the organization scales on top of it. Every workflow built inside Airtable after that point is one more thing that has to be untangled and rebuilt somewhere else whenever the migration finally happens, and the data-cleanup bill at switchover grows right alongside it.
The good news is that the migration paths available by 2026 aren't a single narrow choice. They split into a few distinct categories, each with a different trade-off(). Open-source, self-hosted options like Baserow, NocoDB, or Grist hand back full control over data and cost, in exchange for someone on staff actually running the infrastructure, which makes sense for organizations with at least some in-house technical capacity(). Internal tool builders like Jet Admin and Retool take a different shape: the data becomes an input, and what comes out the other end is a real application with permissions and workflows baked in, and Retool in particular stands out as the strongest fit for engineering teams that need custom internal tools talking to multiple APIs or data sources at once(). Work-management suites like Smartsheet, ClickUp, or monday.com solve a narrower problem well: they're built around tracking tasks and projects, which makes them the right call when the actual need is managing workflow rather than managing data().
None of these options is universally correct, and that's sort of the point. The decision about which path to take is itself a deferred-cost scenario, a smaller version of the exact argument running through this entire piece. The right time to make that call is before the exit penalty compounds any further, not after it's grown large enough to make every option look equally painful.
Why internal teams consistently under-remediate debt even when they recognize it
If the cost of ignoring infrastructure debt is this well understood, why does it keep happening anyway? Not because engineering teams are unaware of the problem. Most of them can point to the exact module or workaround causing the pain. The same team responsible for fixing the debt is also the team responsible for keeping production running today, and between those two, production wins every time.
Debt remediation and operational maintenance are competing for the exact same hours on the exact same calendar. One of those two things has a customer noticing it within minutes if it fails. The other one, if left alone, fails quietly for months before anyone outside the engineering team even notices something's wrong. Given that choice, day after day, sprint after sprint, the loud problem consumes the calendar and the quiet one keeps compounding in the background, mostly unexamined, until the threshold event described earlier finally forces the question.
Sources
- Technical debt is the hidden barrier to enterprise AI | DXC Technology
- Managing Technical Debt in 2025: Strategies for Legacy Systems and Cloud Readiness
- What Is Technical Debt? IT Budget Guide 2026
- The Modernization Debt: What Years of Deferred Change Costs
- How Technical Debt Becomes a Cybersecurity Risk | STACK Cybersecurity
- The hidden drag, quantified: Technical debt’s penalty on value and growth
- Reducing technical debt in 2026 | IBM
- What Technical Debt Means To IT Professionals