Ranking and Prioritizing Technical Debt Findings Before an Engineering Engagement Begins
Score technical debt by business impact, not by how annoying the code feels.
A technical debt assessment before hiring an engineering partner should rank findings by business cost and risk. It should cover architecture, delivery friction, security, dependencies, and tool constraints, producing a dated, scored register with owners and a recommended sequence. The goal is to put work that unblocks growth ahead of work that merely makes the code look cleaner.
Why the pre-engagement moment is the highest-leverage point for ranking technical debt
A founder may start an engagement with a long list of complaints, warnings, and fixes that have been put off. Yet a list is not a brief. Without ranking, everything looks urgent, and the incoming partner can spend the first sprints addressing the most visible weaknesses while leaving the most costly ones unresolved. Improving maintainability can free development capacity, so poor sequencing wastes part of the capacity the engagement was meant to create.
Before work begins, no active engagement sprint is competing for attention. That gives the team room to consider the codebase as a portfolio. SIG’s 2026 prioritization guide distinguishes intentional debt, taken on with a payback plan, from unintentional debt accumulated without visibility or a plan. The assessment is the chance to separate those obligations before the partner inherits them as equals.
Why MVP-era codebases arrive at an engagement carrying predictable, structural debt
The first product built under time pressure often shows that engineers made sensible trade-offs with care. Shipping takes precedence over work whose benefit lies further ahead. The trouble begins when those decisions go unexamined as the product grows. Skipping an admin panel or sending onboarding emails manually can be an intentional, recoverable shortcut. Structural debt is different because new features keep building on it.
Hardcoded configuration and credentials become painful when the team needs to deploy to several environments. When access control is built into each screen, permissions are spread across those screens with no central layer to manage them. Database shortcuts also become harder to sustain. Skipped indexes, missing constraints, and denormalized tables that were acceptable at hundreds of rows can become performance and data-integrity problems at hundreds of thousands. These are foundations the partner must work with.
With little automated testing, later changes are risky and rollbacks cost more, while mixing business logic with presentation makes refactoring harder. These weaknesses often become visible during scale-up, after launch. Performance problems can appear around the first hundred paying customers, integrations become noticeably brittle as use grows, and poor organization slows feature development. The pre-engagement question is therefore not simply which shortcuts exist. It is which shortcuts will compound under the work the partner is about to add.
What "ranking by business cost and risk" actually means — and what it excludes
The most annoying code is not necessarily the most expensive code. A difficult module may rarely change, while a less conspicuous weakness delays every release. Coderio’s 2026 business risk framework measures debt against delivery capability, including lengthening release cycles, defects after changes, and time spent understanding systems. That makes the ranking a business decision.
Lead time shows how long a change takes to reach production. Change failure rate shows how often a deployment causes a problem requiring remediation. Dependency age and known vulnerability exposure reveal a different kind of risk, while maintenance time shows how much capacity is unavailable for new features. Together, these signals connect technical findings to operating consequences. They give stakeholders something more useful than an assertion that the code is bad.
But lines of code cannot show what should come first for the business. Neither can a single composite debt score detached from the code’s role, or cyclomatic complexity in a dormant module. SIG finds the biggest return where code changes often, matters to the business, and has a fragile structure. Ordinary remediation should concentrate at that intersection. Stable, rarely touched code with no planned roadmap contact is often correctly left alone, because cleaning it up consumes capacity without producing a return.
Three prioritization mechanisms that work before an engagement begins
The first mechanism is an impact-versus-effort Debt Quadrant. To apply it, compare the business value of each fix with the effort required. Work with high value that takes little effort goes first, helping the team get going and showing stakeholders a return early in the engagement. Work with low value that takes a lot of effort should wait until later or stay out of the plan. This is a useful first pass.
Fowler’s quadrant helps explain how the debt came about. Was the decision deliberate or inadvertent, and prudent or reckless? Those distinctions shape both the response and the order. Coderio flags reckless-deliberate debt, expressed as “we don't have time for design” without follow-up, as especially damaging because it compounds and erodes trust between engineering and product leadership. Such findings deserve attention near the top even when their effort estimate makes them look unattractive.
The second mechanism is interest-rate scoring, which combines ongoing cost with frequency of change. How much maintenance, delivery drag, incident response, or security exposure does an item create? How often does the surrounding code change? Complex code touched weekly can charge substantial interest, while the same complexity in dormant code may charge almost none. SIG gives a practical example in which a highly complex function is worth refactoring when a planned feature must change it, but not when nothing on the roadmap touches it.
To make that comparison concrete, estimate interest as maintenance capacity consumed, multiplied by developer cost. The principal is the remediation effort. Dividing that effort by the capacity freed up each year gives a payback period, as long as both use units that work together. A big repair may pay off if the team keeps paying for the weakness.
The third mechanism is a scored register that records each finding across five dimensions. Business impact asks whether revenue, users, or critical features are affected, while developer impact shows how much delivery drag the weakness causes. Risk records the consequence of failure, fix cost estimates effort, and urgency identifies deadlines such as a security patch, deprecation, or dependency end-of-life. The scores make trade-offs visible to non-engineering stakeholders. Before engagement, the register needs a date and an owner, even if it is not connected to live codebase signals.
That ownership prevents the register from becoming a historical snapshot mistaken for current evidence. Codacy recommends monthly or quarterly debt-backlog reviews. At pre-engagement, the immediate task is one review against the planned scope to set the initial sequence. The three mechanisms thus serve different purposes.
Why security and dependency debt must be handled as a separate, non-negotiable track
A rarely touched module can still expose a critical vulnerability because risk depends on exposure and attacker incentive. Dormant does not mean safe in this case. SIG ranks security findings and risky open-source libraries higher than they would sit in the usual business-impact ranking. It also recommends triaging new security findings every sprint.
For pre-engagement triage, this means separating security and dependency findings from the main scoring queue. Known vulnerabilities, end-of-life dependencies, and access control gaps should be flagged for engagement-day-one work regardless of their impact-effort score. They cannot wait for a convenient feature to touch the affected code. Architectural weaknesses also need more than automated cleanup because fixing them takes knowledge of the whole system, even where AI tools can tackle duplication or complexity. For a nonprofit, a breach threatens mission continuity through lost donor trust, regulatory exposure, and the disruption of recovery.
What should the incoming engineering partner see in the assessment handoff?
The partner needs a written debt characterization. That artifact should contain a dated inventory of the highest-risk areas, the scored findings, a recommended sequence coordinated with feature work, and a named owner responsible for updates. Each category also needs someone to take charge of it throughout the engagement. Shared concern is not the same as responsibility. Without that distinction, findings can survive every handoff without anyone acting on them.
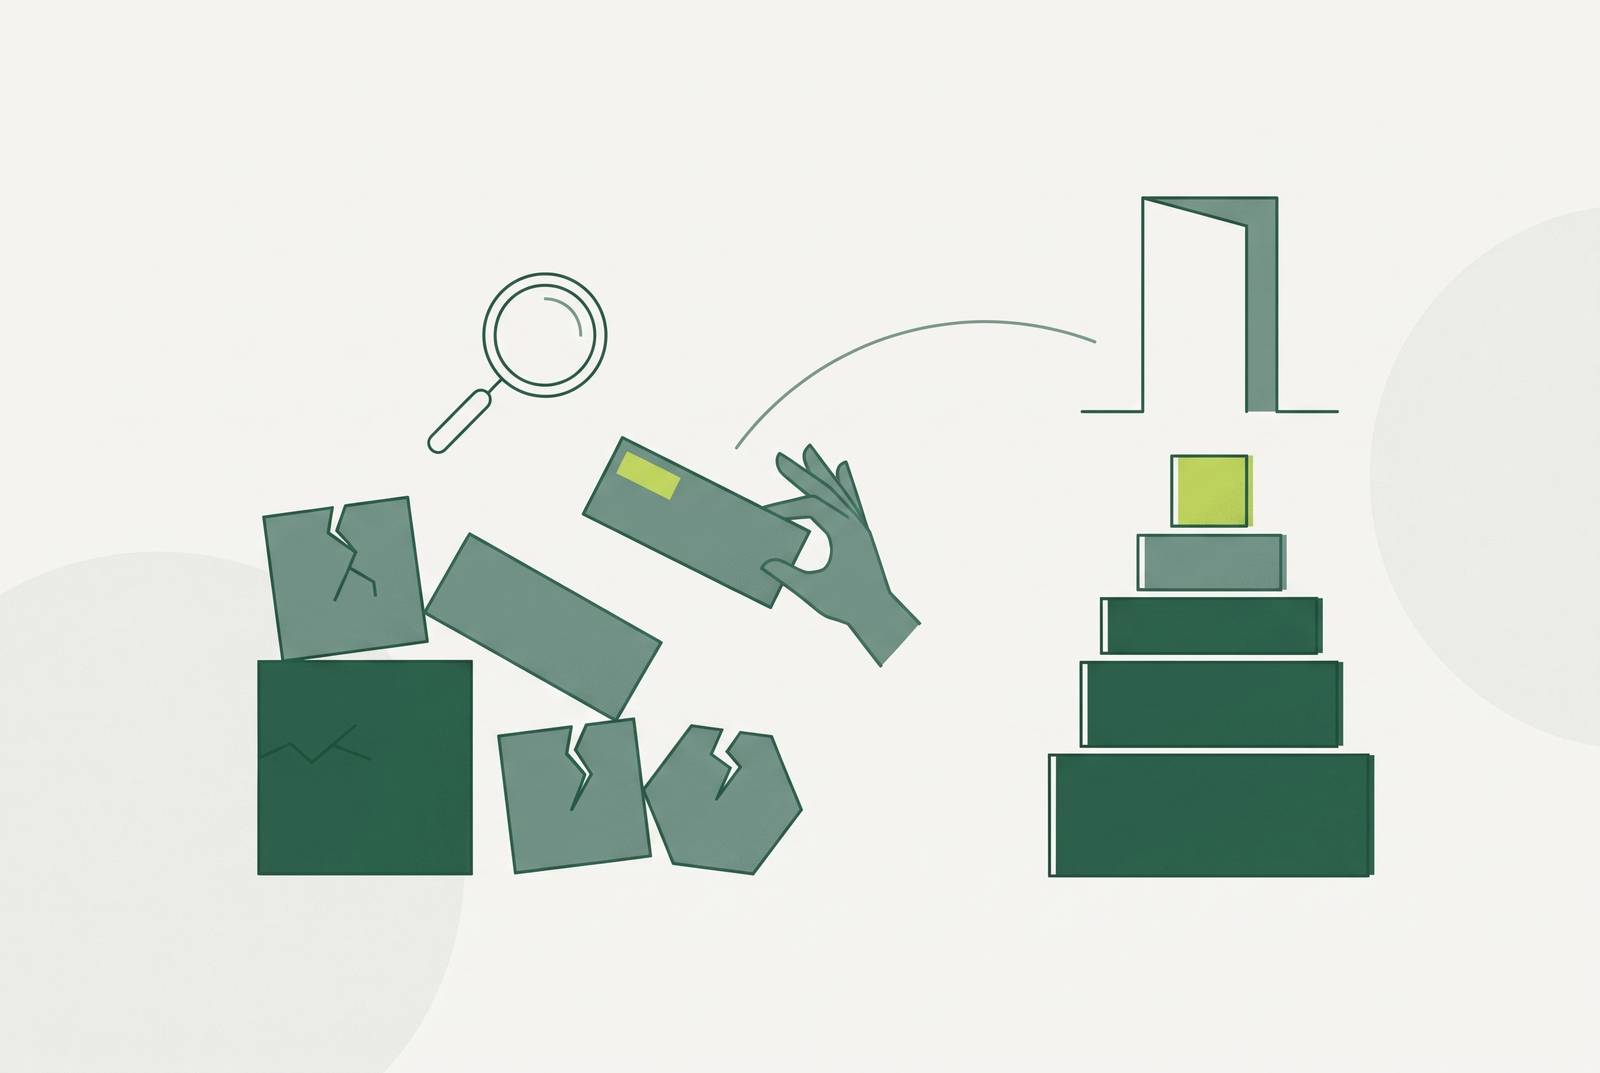
The sequence should separate three kinds of work. “Fix before anything else” covers security findings, end-of-life dependencies, and access control gaps exposing real users. “Fix alongside feature work” covers high-churn, high-impact structural weaknesses that will compound as the partner builds. “Leave for later or leave alone” covers stable, low-churn, or planned-phase-out code with negligible interest payments. These categories turn scores into decisions the partner can use.
The document must also make exclusions visible. An assessment can trigger scope creep when stakeholders treat it as their only chance to fix everything. A ranked inventory should therefore distinguish a known problem from work accepted into this engagement. That boundary helps keep each incoming administrator or developer focused on improving what exists. The handoff preserves the findings and the reasoning behind the sequence.
When the tooling itself is part of the debt — the Airtable case for nonprofit teams
For a nonprofit running operations on a no-code platform, the tool can belong in the debt register too. Vendor lock-in, record limits, and automation caps may constrain what an engineering partner can build on the existing data layer. This is still a business-cost question. Does the platform obstruct planned work, introduce dependency risk, or force spending that the team would otherwise avoid? Those constraints still need to be assessed even when the interface is familiar.
Airtable’s Business tier has a per-seat monthly cost billed annually, with hard caps on records and automation runs. Growing teams can be pushed toward that tier even when they do not need everything it includes. Those limits need to be weighed against the data and workflow needs of the planned engagement. They are not, by themselves, a reason to migrate. The ranking should establish whether the constraint blocks the work before treating replacement as the answer.
Four alternatives offer different ways to address that constraint. Baserow’s core open-source edition has a permissive license and is self-hostable, while premium and enterprise modules have separate licenses. When self-hosting, the row limits and API restrictions that can frustrate Airtable users at scale are not a factor. Baserow states that it is GDPR, HIPAA, and SOC 2 Type II compliant. NocoDB instead turns SQL databases into smart spreadsheets, making it relevant for teams that want direct management of large datasets and database-level portability.
Noloco addresses a different need through custom applications connected to existing databases or its built-in tables. Its tailored interfaces can support specific nonprofit workflows. Grist combines spreadsheet flexibility with a database structure and can be self-hosted. That makes it relevant where data residency is a concern. For teams with data residency or HIPAA requirements, evaluating self-hosted options such as Baserow, NocoDB, and Grist belongs before the engagement, when vendor dependency can still be addressed before it blocks planned work.
Running the triage without a dedicated technical lead on staff
The obvious objection is that the team is hiring a partner precisely because it lacks technical leadership. Does ranking debt require that missing person first? Not for a useful starting document. Business impact, delivery drag, risk, cost, and urgency can be explored through structured conversations. The founder explains what happens to the product, while people who know the code help explain the weaknesses behind those effects.
To begin that conversation, document where customers notice the product breaking or slowing down. List the integrations, dependencies, and third-party services it relies on, flagging those that caused outages or required emergency patches in the last year. Ask former developers, contractors, and freelancers which areas they kept warning people to leave alone. SIG treats those warnings and developers’ knowledge of painful areas as useful input to validate against change data.
Separate existing customer-facing problems from friction felt only inside the team, giving the former priority regardless of fix cost. Record what is known and make clear which parts are estimates. The incoming partner can then validate the ranking, refine remediation effort, and take ownership of the agreed work. A perfect register is not the entry requirement. A ranked hypothesis gives the engagement a defensible starting point instead of using the first sprint to discover which problems deserve attention.